AI & ML
When Not to Use Similarity Search in a RAG Pipeline
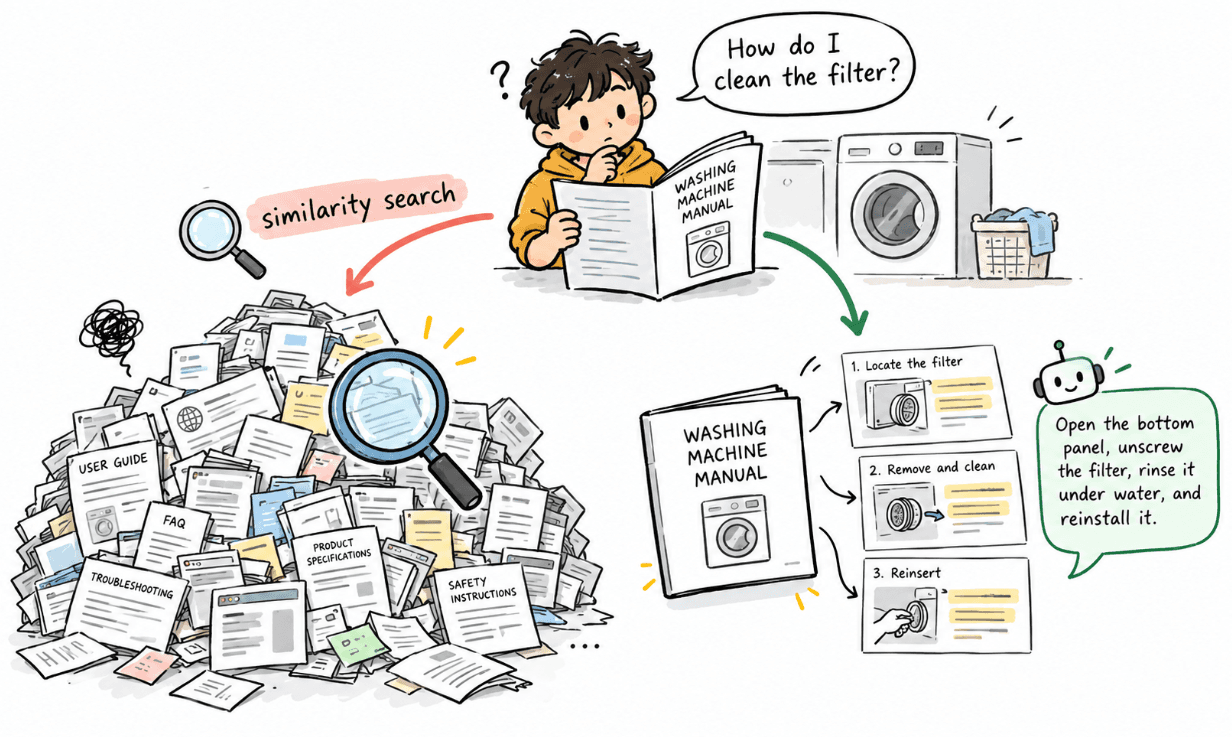
When we learn about RAG, the usual flow feels very natural. A user asks a question, we create an embedding, search the vector database…
NCNavindu Chathuranga · · 5 min read
Writer6 articles
Software Engineer @ Enlear
When we learn about RAG, the usual flow feels very natural. A user asks a question, we create an embedding, search the vector database…
What If You Could Control Every AI Call From One Place? A practical guide to putting one layer between your application and AI models, so you can track costs, switch models, manage access, and …
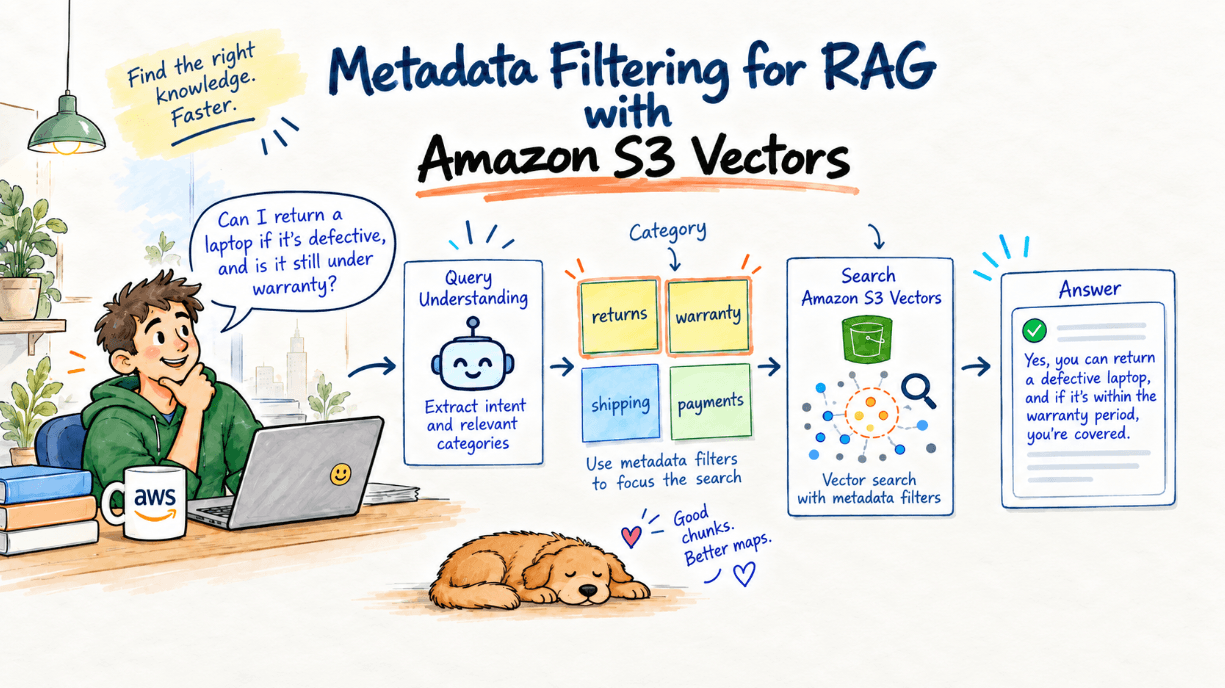
Beyond Similarity Search: Metadata Filtering for RAG with Amazon S3 Vectors Semantic search is one of the most useful parts of RAG. A user does not need to ask a question using the exact same words …
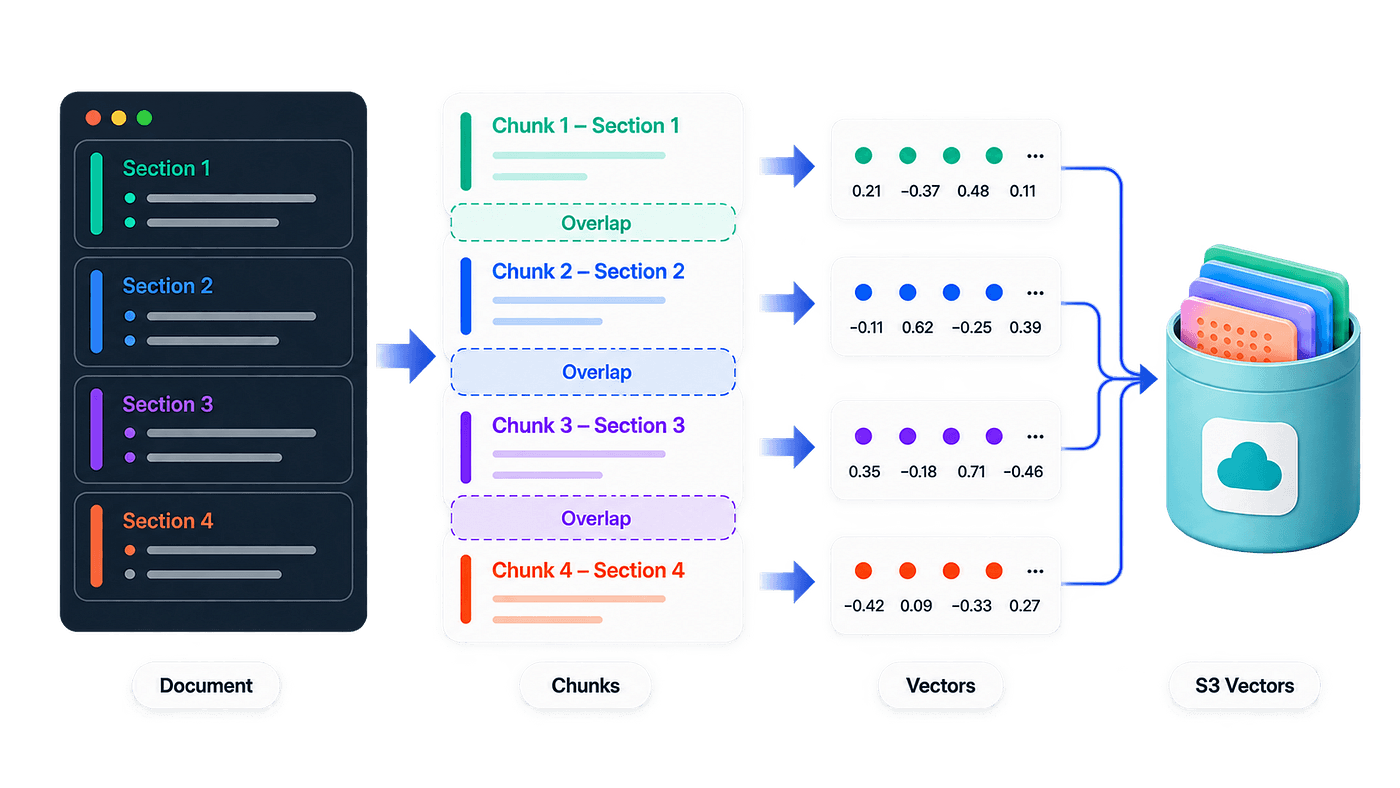
Building a Structure-Aware RAG Chunking Pipeline with Amazon Bedrock and S3 Vectors A RAG system can use a good embedding model and a reliable vector database, but the results can still feel less …
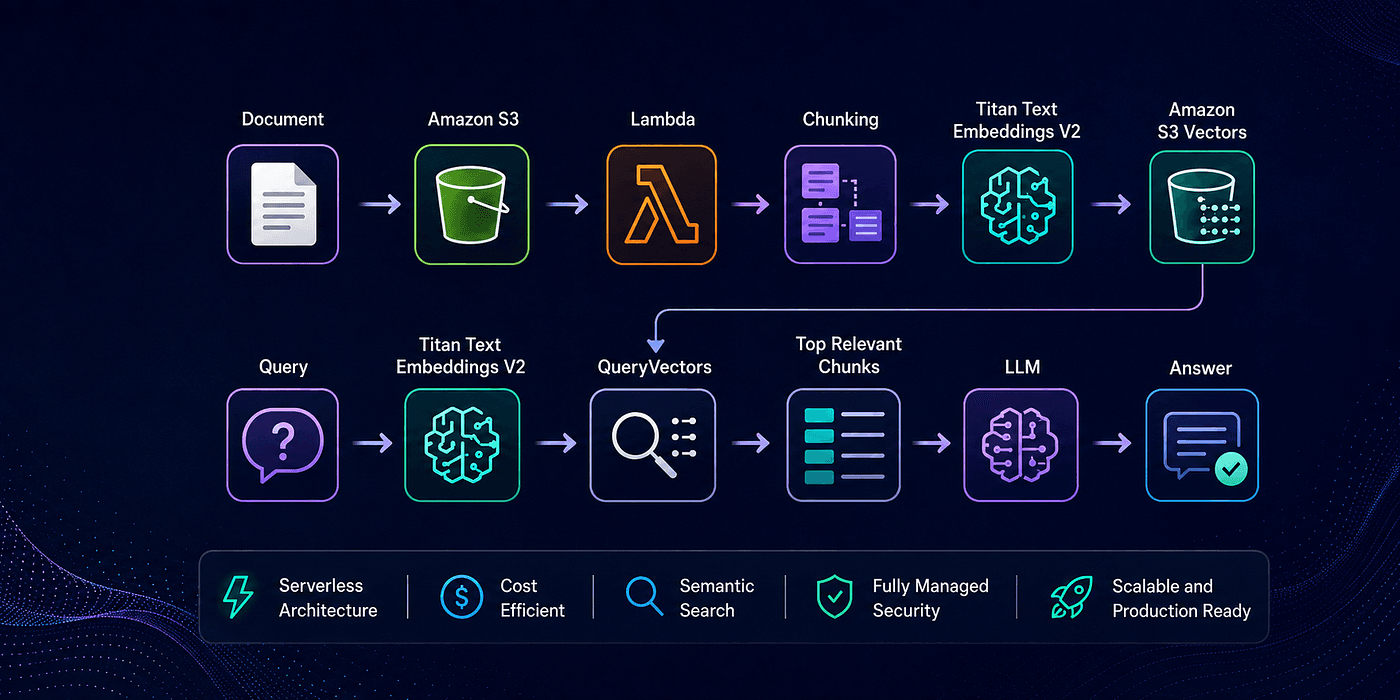
Building a Serverless RAG Pipeline with Amazon S3 Vectors and Amazon Bedrock When I first learned about Retrieval-Augmented Generation (RAG), the architecture looked simple: Store some documents → …
Prompt Injection in AI-Powered Applications How to Test Against Prompt Injection in AI-Powered Applications? Introduction Every AI system operates on instructions. But what happens when someone slips …